一个好的问题描述有利于社区小伙伴更快帮你定位到问题,高效解决你的问题
【TiDB 使用环境】生产环境
【TiDB 版本】 v7.5.6
【部署方式】机器部署
【操作系统/CPU 架构/芯片详情】centos7.9
【机器部署详情】40C 128G
【集群数据量】
【集群节点数】6 server + 10 tikv + 5 tiflash
【问题复现路径】做过哪些操作出现的问题
【遇到的问题:问题现象及影响】
应用日志报错,tiflash 重启
【资源配置】进入到 TiDB Dashboard -集群信息 (Cluster Info) -主机(Hosts) 截图此页面
【复制黏贴 ERROR 报错的日志】
查看 tiflash 日志:
[err=“other error for mpp stream: Code: 0, e.displayText() = DB::Exception: Receiver state: ERROR, error message: Exchange receiver meet error : Code: 0, e.displayText() = DB::TiFlashException: Memory limit (total) exceeded caused by ‘out of memory quota for data computing’ : would use 100.29 GiB for data computing (attempt to allocate chunk of 1179648 bytes), limit of memory for data computing: 100.29 GiB. Memory Usage of Storage: non-query: peak=15.53 GiB, amount=3.23 MiB; query-storage-task: peak=2.02 GiB, amount=401.08 MiB; fetch-pages: peak=0.00 B, amount=0.00 B; shared-column-data: peak=2.02 GiB, amount=401.08 MiB., e.what() = DB::TiFlashException, e.what() = DB::Exception,\ngithub.com/pingcap/tidb/pkg/executor/internal/mpp.(*localMppCoordinator).handleMPPStreamResponse\n\t/workspace/source/tidb/pkg/executor/internal/mpp/local_mpp_coordinator.go:634\ngithub.com/pingcap/tidb/pkg/executor/internal/mpp.(*localMppCoordinator).receiveResults\n\t/workspace/source/tidb/pkg/executor/internal/mpp/local_mpp_coordinator.go:510\ngithub.com/pingcap/tidb/pkg/executor/internal/mpp.(*localMppCoordinator).handleDispatchReq\n\t/workspace/source/tidb/pkg/executor/internal/mpp/local_mpp_coordinator.go:463\ngithub.com/pingcap/tidb/pkg/executor/internal/mpp.(*localMppCoordinator).dispatchAll.func2\n\t/workspace/source/tidb/pkg/executor/internal/mpp/local_mpp_coordinator.go:368\nruntime.goexit\n\t/usr/local/go/src/runtime/asm_amd64.s:1650”]
【其他附件:截图/日志/监控】
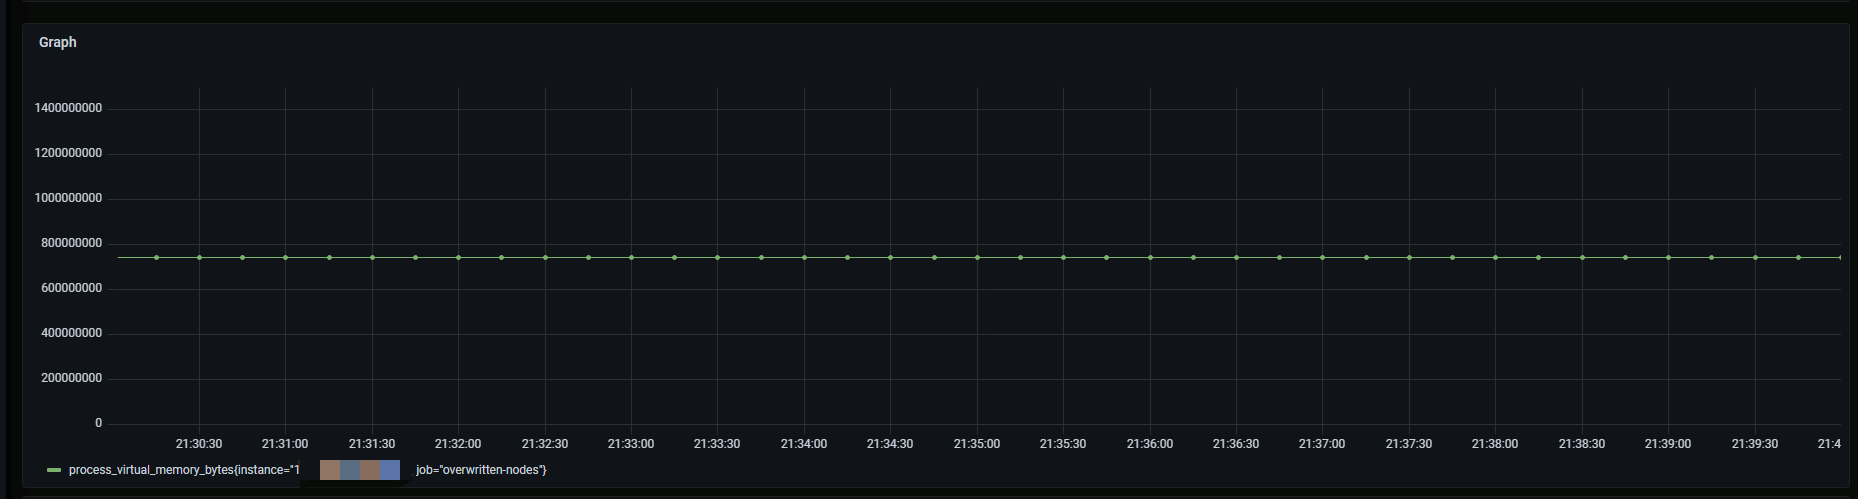
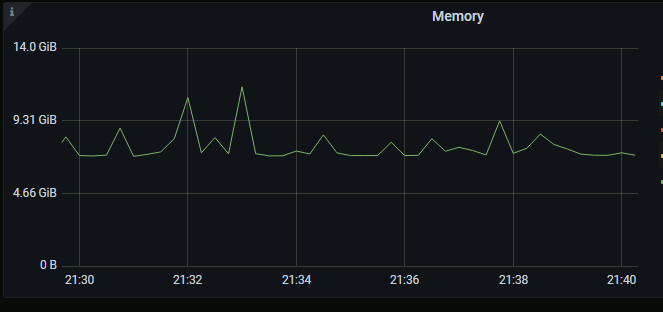
实际当时的内存使用率截图: